Legal AI systems usually fail on four early decisions, not on model quality: how memory is scoped and governed, where private text is allowed to go, what a multi-step agent really costs, and whether a clause reaches the lawyer word for word. Each is cheap to settle on paper and expensive to retrofit.
This article sets out a position on each. Where a figure is an estimate and not a measurement, it says so.
1. Memory: three areas, one contract, a storage choice made by benchmark
Legal memory is not one store. It is three areas, each with its own rule for who may write and who must confirm:
| Area | What it holds | Rule |
|---|---|---|
| Personal preferences | Style and defaults | The user confirms their own entries |
| Matter memory | Case notes, positions, working summaries | Off until the matter’s responsible person sets its policy; new entries are confirmed by an authorised reviewer |
| Organisation knowledge | Playbooks, templates, standards | Read-only in daily work; published through an approval workflow |
Three controls make this auditable. Agents may search, read, propose and correct, but only people confirm, reject, restrict or delete. A confirmation is bound to the exact content and version the reviewer was shown, so text cannot change after approval. Every entry keeps its source and speaker, and anything derived from a document is switched off if that document is withdrawn. Retention periods, legal holds and complete deletion when a matter closes are set per area, not left to the storage layer.
The application talks to memory only through a stable memory contract, backed by one memory core that owns scope, provenance, retention and deletion. The storage under it stays replaceable.
Storage is a decision to benchmark, not to assume. SQLite with full-text search is the lightest baseline: no database server, no embedding model, the same code on a laptop, in the cloud and in an air-gapped site. Its limit is that it is single-node. A block volume attaches to one instance, so it does not suit several replicas or short-lived runtime sessions, and heavy parallel writes queue behind one lock. Aurora PostgreSQL costs more but adds failover, backups and concurrent writes, and uses the same relational model. Agree the pass criteria first (for example a number of concurrent writers, a p99 latency and a recovery-time limit), test recall, latency, memory, concurrency and recovery on both, then choose. Also settle whether air-gapped installs are a signed client commitment or a wish: if no client requires one today, building a portability layer for it now may not be justified. In one worked three-year cost model the two differed by under $2,000.
Retrieval is keyword-first. Scope filters, metadata, entity and relation matching, full-text search with BM25 ranking, and validity dates cover most memory lookups without embeddings. Semantic search stays optional, added only if a recall test shows a clear gain. Keyword search has one catch: it matches words, not meaning, so anything looked up by category (“find all templates”) must carry that word in its stored text.
2. Sovereignty and masking: one rule, applied at every model call
The rule: everything private that goes to a model is masked; public court decisions and statutes are not. That includes the document being edited, contracts sent for extraction, and text sent for embedding or reranking, because each of those is a model call. The stored index and the case-management record keep the real values.
The masking layer is the organisation’s own detector, running in the application tier before text reaches any model. Placeholders such as [[PERSON-1]] are stable within one request, so the instruction, the retrieved passages and the document all use the same label for the same person. Find, replace and comment then work on placeholders, and the application restores the real values in the result. Generic cloud PII services fit this badly: language coverage is limited (check German in particular), and storage scanners inspect buckets rather than prompts.
Four caveats keep the rule honest:
- It is a detector, not a guarantee. A missed name still reaches the model. State the measured recall on real German legal text instead of promising that nothing leaks.
- Masking must sit before every model call, not only the answering one. Reranking is a model call too, so passages are masked at the tool boundary, when the agent fetches them, and before they are ranked. Ranking masked text may rank worse; measure it.
- Masked embeddings trade away cross-document matching. Placeholders restart for each request, so
[[PERSON-1]]in one document is not[[PERSON-1]]in another, and a search for a person’s real name finds nothing. Test recall before making masked embedding a rule. - A restoring step can corrupt text if the model edits or drops a placeholder. Validate that every placeholder survives before restoring. Streaming makes this harder, because a placeholder can be split across two chunks and the restoring step must hold back a partial one.
Region pinning is per service, not one switch. A service control policy blocks calls outside the chosen region. Model invocation then needs an in-region inference profile: some of the newest models are offered only through global or US profiles and cannot be used under a European policy, so restrict the model list to models whose profile list includes an EU profile, checked from the target region with the provider’s profile lookup. Guardrails has its own EU profile, while Textract and similar document services are held in the region by region setting and the policy. Name the control for each service.
3. The economics of agent loops: model calls per request, not tokens per question
A cost model built on one call per question will be wrong for any flow where the agent calls tools. Each model call re-sends the system prompt, the question and every earlier tool result, so input tokens add up across calls:
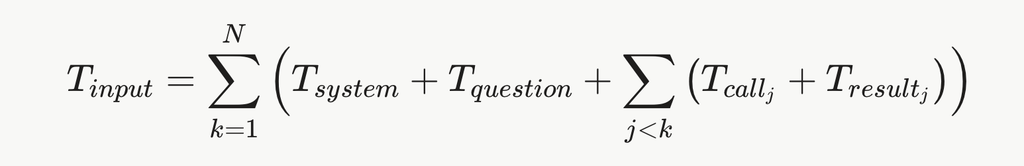
A worked example with four calls:
| Call | What is added | Input tokens billed |
|---|---|---|
| 1 | System prompt and question | 3,000 |
| 2 | Retrieved contract (15,000) | 18,500 |
| 3 | Playbook (3,000) | 22,000 |
| 4 | Memory lookup | 26,000 |
| Total | 69,500 |
That is about 2.7 times the 26,000 tokens a single call carrying the same context would bill. The growth is real but not explosive at four calls; it grows with longer loops and larger retrieved text.
It becomes money once priced. At $2 per million input tokens the example costs about $0.14 in input; at $3, about $0.21; at $15, about $1.04. For 5,000 such interactions a month that is roughly $700, $1,050 and $5,200 of input cost, before output tokens. “Tens of thousands a month” needs either far more traffic or a premium-priced model on every call. The honest statement is that agent loops multiply input cost by a small factor, and the factor must be measured.
What to model and cap:
- Model calls per request, tokens per call, and the share of calls that reach a premium model, per use case.
- A hard turn limit and a cost limit per request, and especially per scheduled or event-triggered agent that runs with nobody watching.
- Tiering: send routine steps to a smaller model and keep the premium model for the final analysis.
In a three-year cost model for 300 users, replacing a one-call assumption of 8,000 input tokens with a loop averaging three times that would roughly double the language-model line. That figure is an estimate from the model’s own split of input and output cost, not a measurement. Check the regional rate limits for the chosen models too: if on-demand quotas cannot carry peak concurrency, reserved throughput changes the cost model.
4. Verbatim precision without carrying the whole contract
Summarising is the usual fix for token growth, and in legal work it is often unacceptable: a lawyer reviewing a liability cap needs the exact words. Decide task by task: reviewing or redlining a clause needs exact text, while portfolio search or deadline tracking can run on structured fields. Only the first needs the heavier handling below. Three patterns keep the words and drop the cost.
A. Use and prune. Once the model has used a retrieved clause to draft its change, replace the full text in the history with a receipt that names the clause and its content hash. Two cautions. Editing earlier history changes the prompt prefix, which breaks the cache from that point on, so prune at a turn boundary and cache only what comes before it. And the receipt must point to a retrievable copy, because the model cannot re-check text it can no longer see, and the audit trail needs the original.
B. The document stays outside the conversation. Keep the working contract in a store and give the agent narrow tools, such as read a clause by id and patch a clause by id. The model then reads and rewrites a few hundred tokens at a time, and every patch records who changed what.
C. Retrieve clauses, not blocks. Cut documents at their own structure: numbered clauses, sub-clauses, schedules. One clause is one chunk, a sub-clause carries its parent’s title, and only a clause longer than the limit is split, at sentence ends. A fixed sliding window of about 1,000 characters, common in general-purpose retrieval kits, cuts clauses mid-sentence. In a test, a sample contract went from three chunks to nine, one per clause. The saving depends on the corpus, so measure it before quoting a percentage. Two limits remain: similarity search is not exact, so a request for a named clause (“the cap in 14.2”) should look it up by clause number, and retrieved excerpts must be built into that call only, not appended to the saved session history.
5. Prompt caching: what breaks the prefix and what does not
Prompt caching bills a repeated prefix at a fraction of the normal input price, but only when the start of the prompt matches exactly. Appending new tool results to a conversation does not break that: everything before them is unchanged, so earlier turns can still be read from cache. What breaks it is changing something earlier in the prompt.
So the layout rule is:
- Static prefix, cached: system instructions, tool definitions, organisation standards.
- Cache point.
- Dynamic suffix, not cached: the masking table, the user’s turns and the retrieved clauses.
Things that break the prefix: putting a per-request value such as a matter number or masking map above the cache point, swapping examples into the system prompt, and pruning earlier history (section 4). Practical limits apply: a minimum prompt size before caching starts, a short expiry that depends on the model and settings, and support that varies by model. Some agent toolkits expose caching for the system prompt and tool definitions only, so caching the growing message history needs extra work. Quote a hit rate only from a measured run.
Checklist, and what to measure before trusting a number
| Domain | Vulnerable pattern | Standard |
|---|---|---|
| Memory storage | A storage choice fixed before testing, or single-node storage under multi-replica compute | One stable contract; SQLite or managed PostgreSQL chosen by benchmark |
| Memory governance | Flat store; agents or users confirming their own proposals | Three areas with their own rules; confirmation bound to content; audit log |
| Retrieval | Embeddings required for everything | Keyword-first; semantic optional and tested |
| Masking | Masking only the answering call; raw documents sent to edit or extract | One rule at every model call, including rerank and embedding; measured recall |
| Region control | One phrase (“EU profile”) for every service | Control named per service; model list limited to models with an in-region profile |
| Agent cost | One-call token assumption | Calls per request, tokens per call, turn and cost caps |
| Agent history | Raw document text left in the conversation | Retrieve by clause, build excerpts into one call, prune at turn boundaries with a retrievable copy |
| Caching | Per-request values above the cache point | Static prefix, cache point, dynamic suffix |
Seven numbers in this article are estimates until measured:
- Masking recall on real German legal text, and its effect on retrieval and ranking.
- Masking latency (p95 per 10,000 words) and whether streaming still works.
- Model calls per request and input tokens per call for each agent flow.
- Cache hit rate in a real run, with the cache expiry actually in use.
- Token reduction from clause-level retrieval on the firm’s own contracts.
- Recall and concurrency of the chosen memory store at realistic volume.
- Whether regional on-demand rate limits carry peak load, per model.